Capabilities
A few of the things you can do in just a few lines of code
Focus (Zoom + Crop)
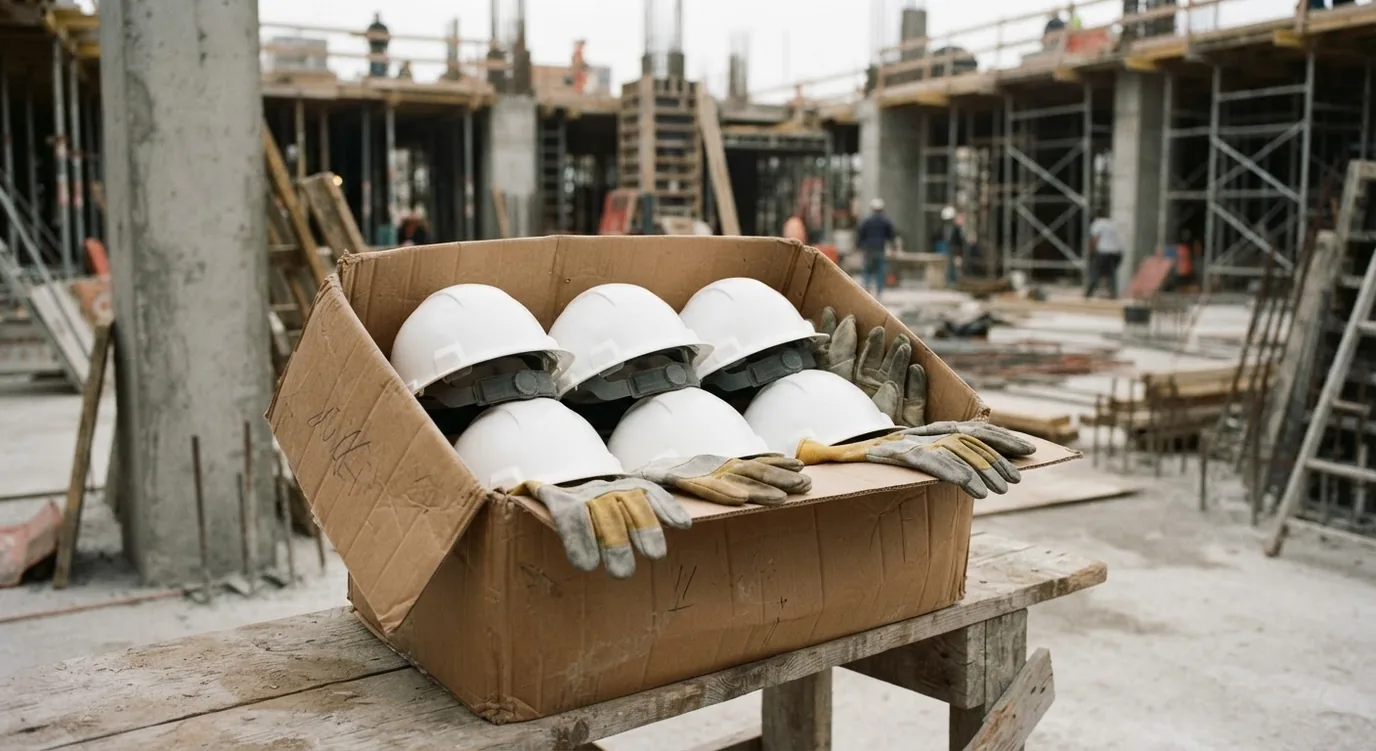
@perceive(model="isaac-0.2-2b-preview", max_tokens=4096, expects="box", tools=True)
def detect_ppe(frame_path: str):
return (
image(frame_path)
+ text(
"Detect and localize the following PPE: helmets, gloves, closed-toe shoes, and protective eyewear. "
"For each item, identify all instances with bounding boxes. "
"If any required PPE is missing for any person, alert me and specify exactly which items are missing."
)
)
detect_ppe("construction_site.png")
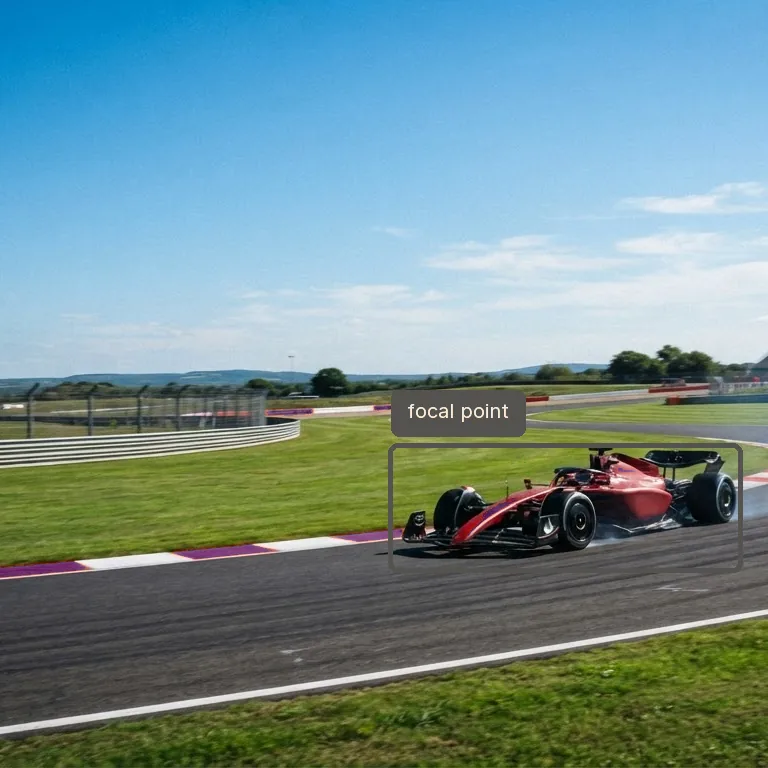
Conversational Pointing
text_prompt = "Identify single focal point of the scene. Be concise."

@perceive(model="isaac-0.2-2b-preview", expects="box", allow_multiple=True)
def focal_point(frame_path: str):
    scene = image(frame_path)
    return scene + text(text_prompt)

focal_point("f1.jpg")
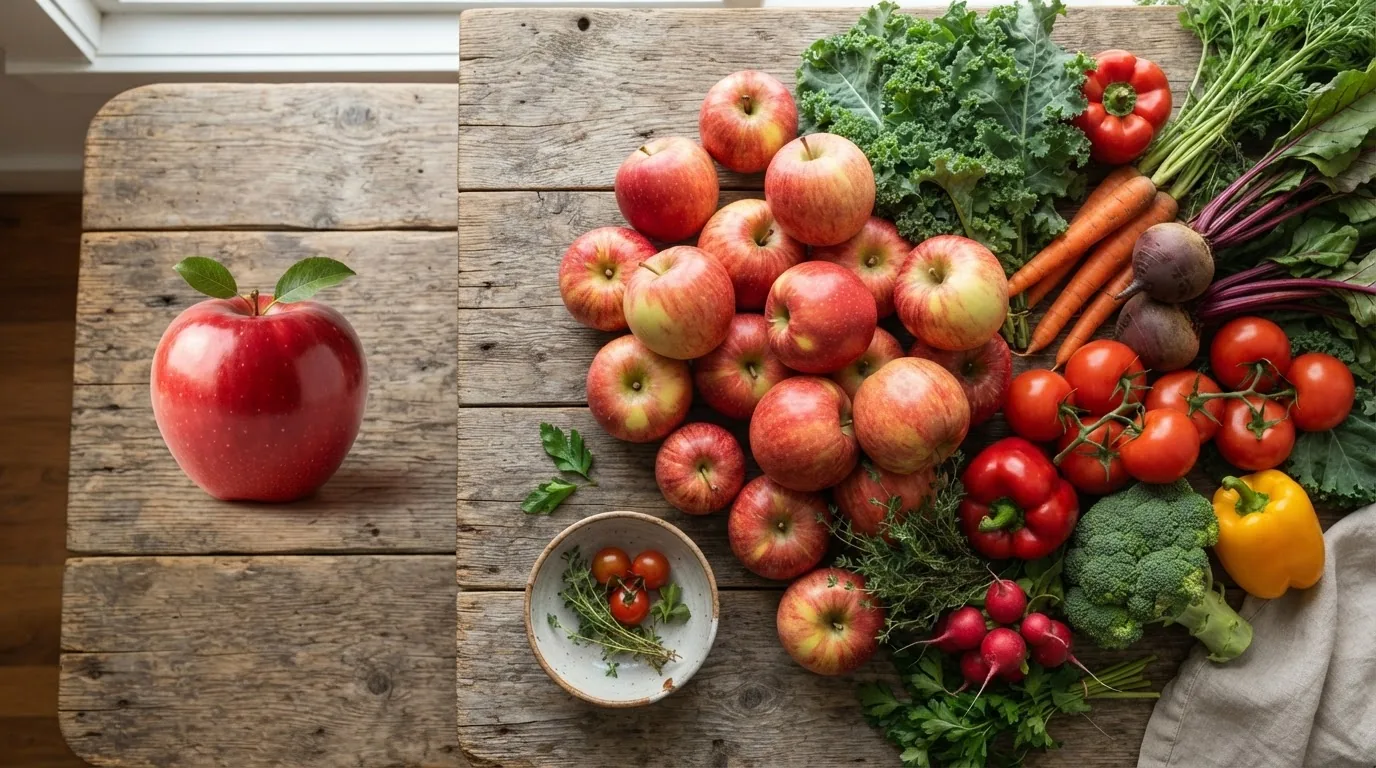
In-Context Learning
@perceive(model="isaac-0.2-2b-preview", expects="box", allow_multiple=True)

def evaluate_produce():
    apple_example = "apple.jpg"
    target_scene = "fruits.webp"
    return (
        apple_example
        + text("This is Category 1. Action to take: cut into slices.")
        + target_scene
        + text(
            "For every instance of Category 1, output a bounding box labeled with the action to take."
        )
    )

evaluate_produce()
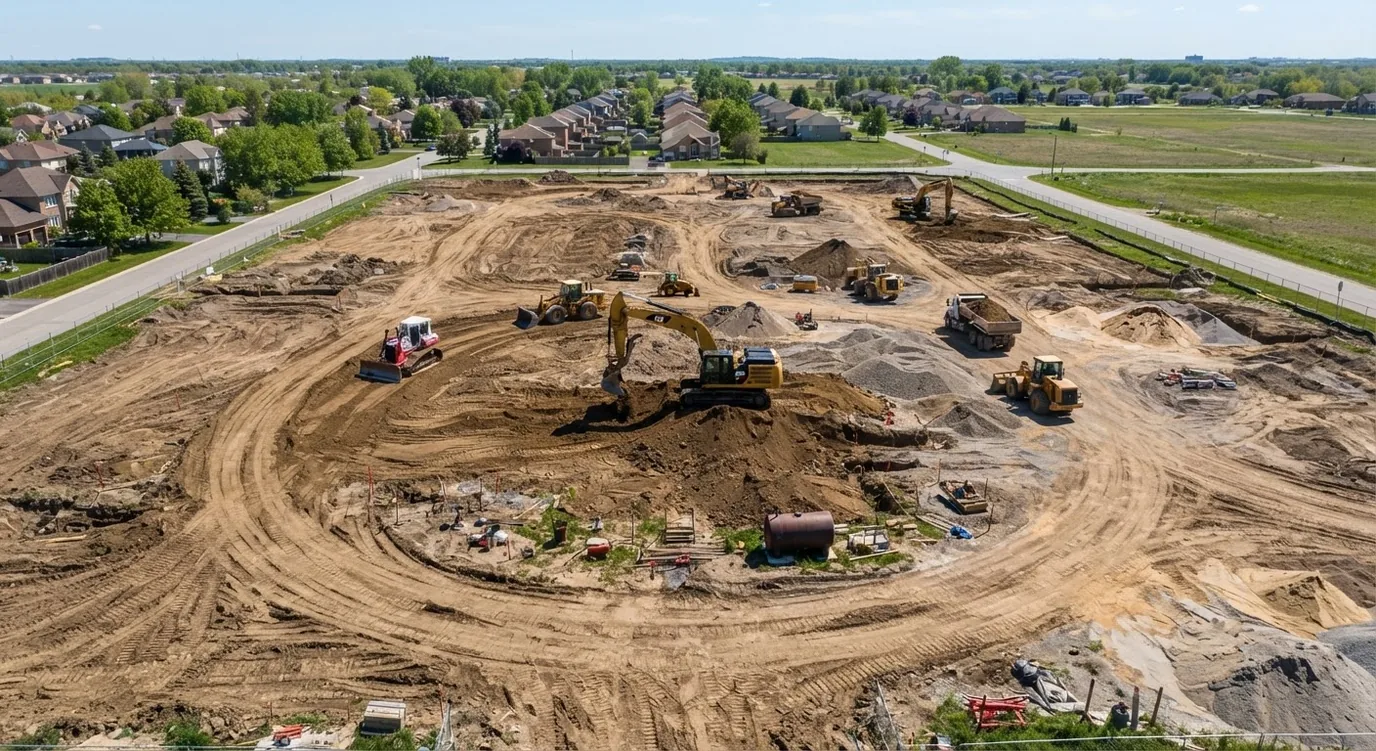
Object Detection
detect(
    image_obj="construction-site.jpg",
    classes=["heavy equipment"]
)
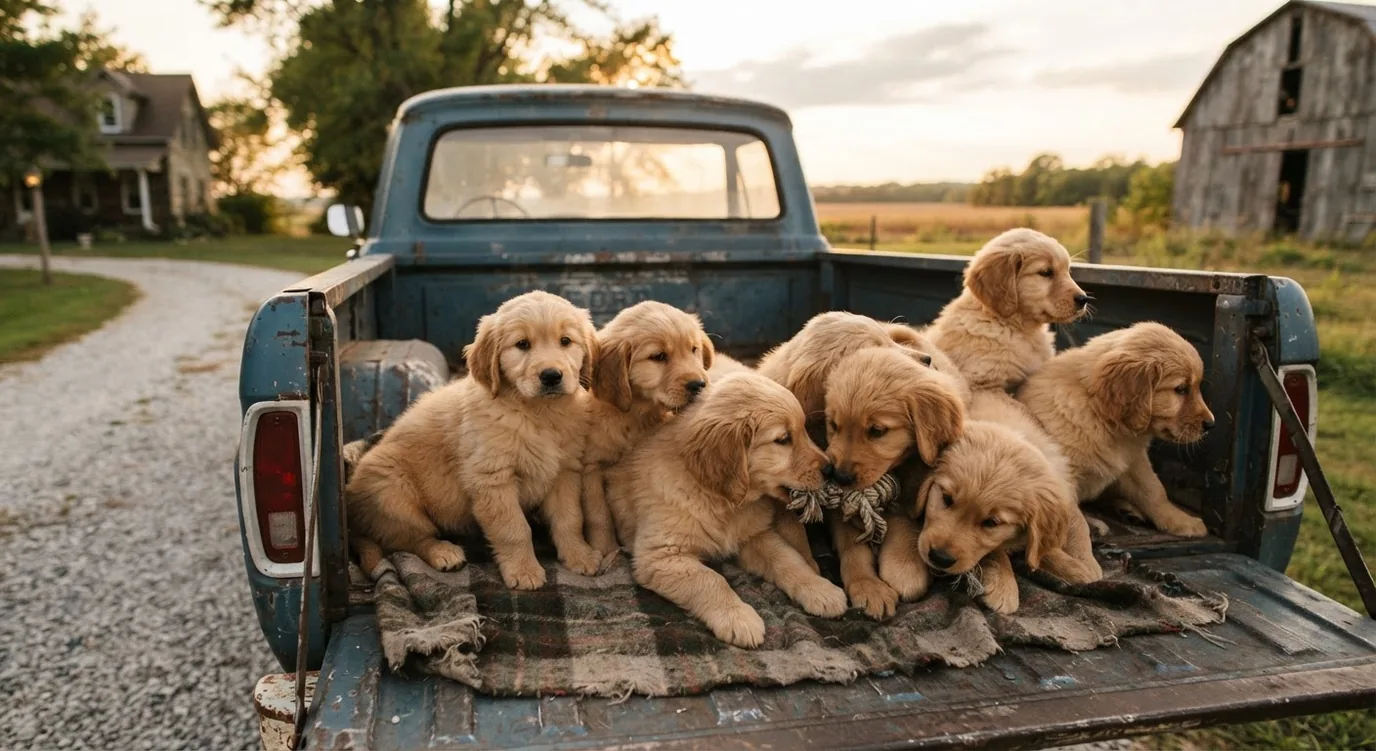
Counting
text_prompt = "Help me count the puppies. Point to each."

@perceive(model="isaac-0.2-2b-preview", expects="point", allow_multiple=True)
def count(frame_path: str):
    scene = image(frame_path)
    return scene + text("Help me count the puppies. Point to each.")

count(puppies.jpg)
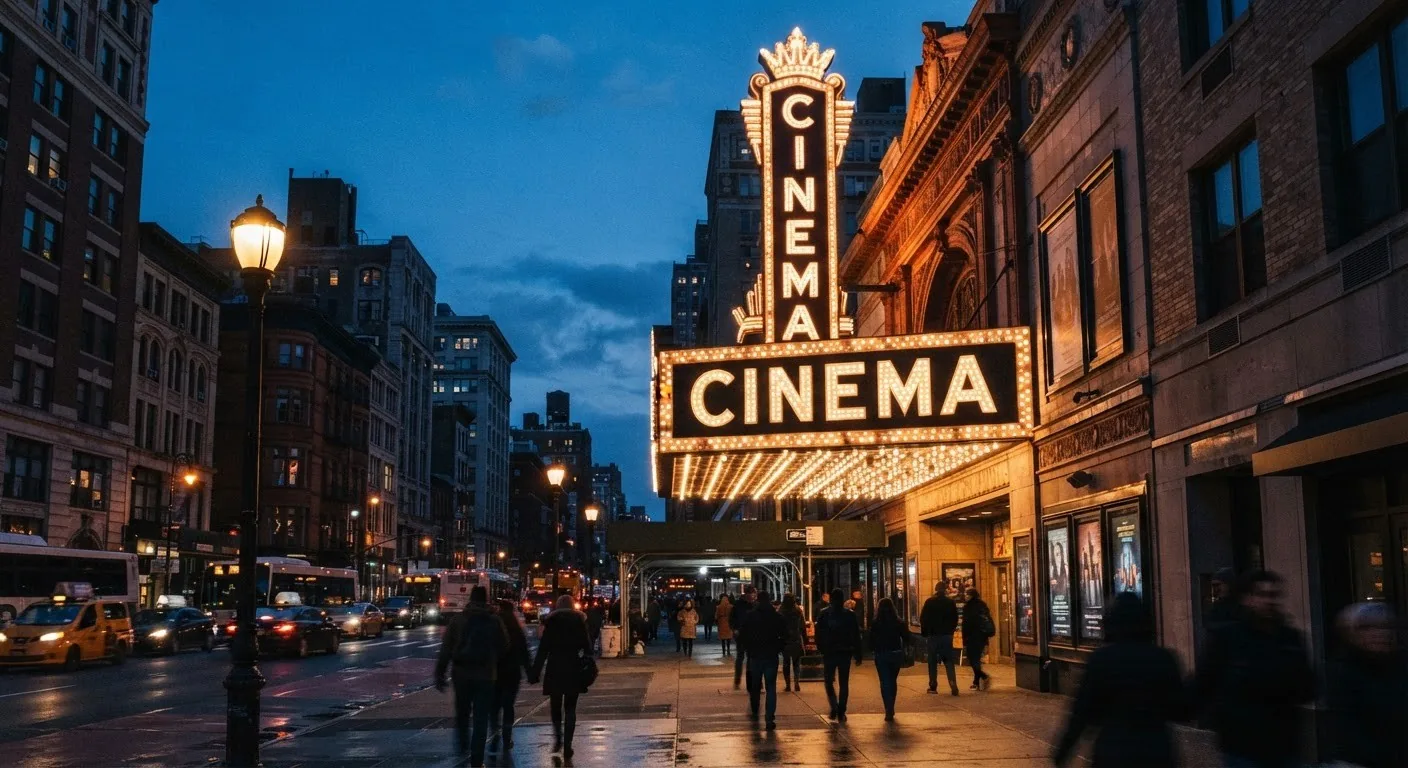
Optical Character Recognition
ocr(
    image_obj="radio-city.jpg",
    prompt="Read any signs."
)
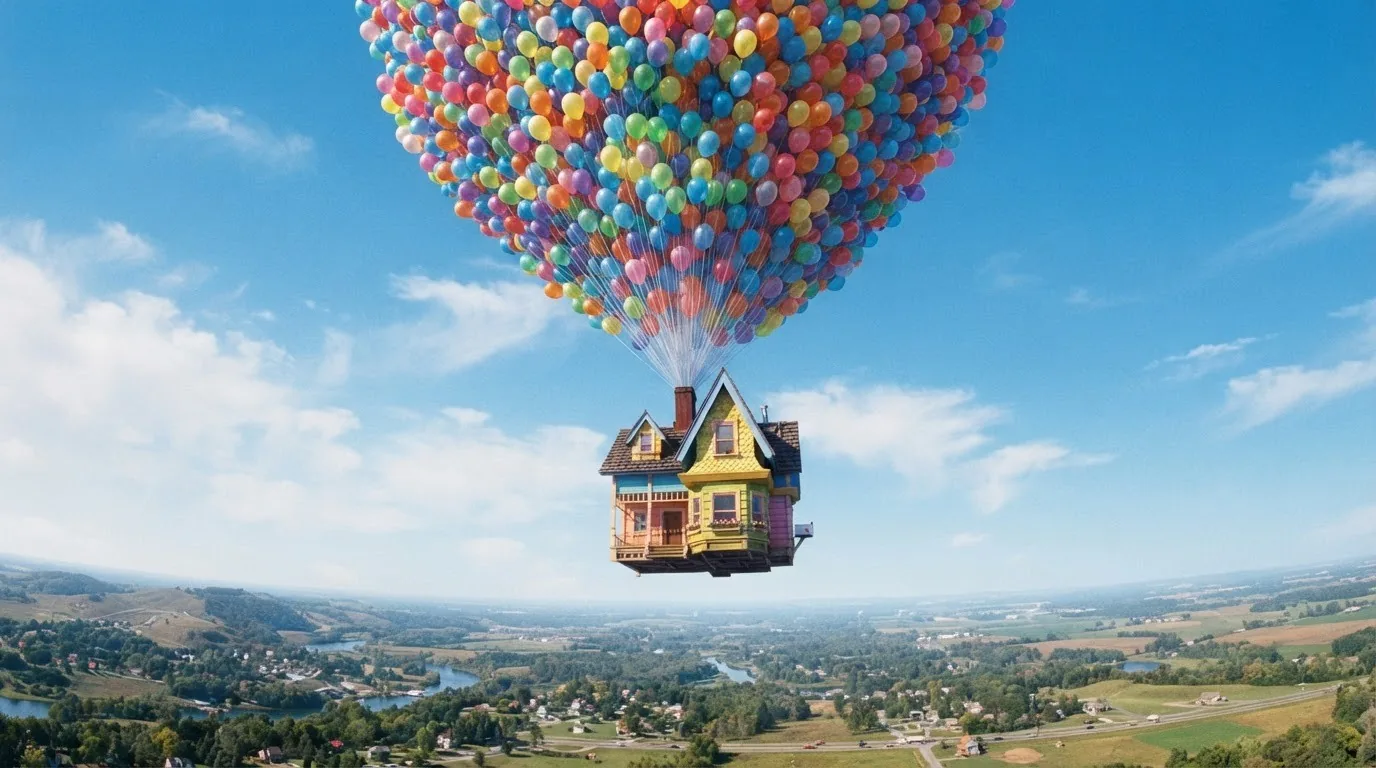
Captioning
caption(
    image_obj="up.jpg",
    expects="text",
    style="concise"
)
Cost Calculator
$1.2900/1M in · $2.5900/1M out
Liss Loop 1.0
Total per request
$0.0205
15.744 tokens / request
2 fps
dynamic sample rate · 120 frames
Prompt14 tok~$0.0000
Video in15,600 tok$0.0201
Output130 tok$0.0003
120 frames, each at 640×416.
Video
Prompt
Video is sampled at up to 2 fps into a fixed patch budget, so longer clips add frames only until that budget fills — then tokens plateau.
cost = (tokens / 1M) × rate — token counts mirror the Liss Loop 1.0 tokenizer: images scale with resolution up to a per-image patch budget, and video is sampled at up to 2 fps into a per-request budget, so video tokens plateau as frame rate and duration climb. Planning estimates only; exact counts come from the SDK.